Showing posts with label VR. Show all posts

Monday, March 21, 2016

Unity 5.3 + Leap: A Look at Orion

A while ago I posted a demo about raising your hand to get a character's attention using the Leap motion.  I was asked recently to take a second look at this demo as the code in that example appears to no longer work using Leap Motion's Orion release. I had not downloaded Orion yet, so this seemed like a good excuse to do so.

After updating everything, I took a look at one of the featured examples, Blocks and my first impression was quite good. This was by far the best hand tracking I have experienced with the Leap.  Thumbs up for sure.

Next I started assembling my own scene to see if I could get the Orion hands to display. I created a new project, set the project build settings for VR (Edit > Project Settings > Player, then ensured that Virtual Reality Supported was checked), and created  a basic scene with plane, a cube, and a directional light.  After importing the  LeapMotion_CoreAsset_Orion_Beta_4.0.1 package, from the LeapMotion assets, I dragged the Prefab > LMHeadMountedRig into the scene.


I gave it a quick test run, but no hands. I quickly realized that I had not followed steps 4 and 5 of the setup guide  to properly add the hand models, both to the scene and to the Hand Pool script attached to the LeapHandController.


After adding the hand models, I gave it a test run and I had hands in the scene.


Now back to the original question, could I  replicate the hand waving demo I created for my earlier post using Orion. In that demo I had a single character idling, minding his own business who, when the user raises their hand,  waves back with a speech bubble appearing saying “Hello, there!”.

I next added a rigged character and the speech bubble.  For the character motion  I used the same animation and animation controller as in the previous demo.


Finally I imported the wavehello.cs script.  After importing the wavehello.cs script, the first error I needed to address was that the namespace name HandController could not be found.

From the short example posted in the setup guide, it appears that the HandController has been replaced by LeapProvider.

The note on that page, says
" In almost every case, you should get Frame objects from the scene’s LeapProvider object. The LeapProvider transforms the frame data into the proper frame of reference. If you get a frame from the Leap.Controller object, the data will still be in the Leap Motion frame of reference and will not match the hands displayed in the scene."

To that end,  the next step was to create a Frame object and  get the CurrentFrame.

Frame frame = provider.CurrentFrame;


Then to get the hands, I looked for each Hand object in the frame.

foreach (Hand hand in frame.Hands)

And just as I did before, I looked at the Y position for each Hand object, and compared it to the Y position of the CenterEyeObject. To simplify things a bit, I only looked at the right hand (hand.isRight) so that I don't need to account for the situation where one hand is up and one hand is down.

The other change from the old script here is that you no longer use the GetPalmPosition() method and instead simply use hand.PalmPosition.y. Here is the  new Update function:


void Update()
{

  // Get the current frame.
  Frame frame = provider.CurrentFrame;

  foreach (Hand hand in frame.Hands){
    if (hand.IsRight){

      if (hand.PalmPosition.y >= centerEyeAnchor.transform.position.y - 0.03f){
        anim.SetTrigger("Wave");
        changeMenuDisplay(speechbubble, 1);
        Debug.Log("Hand above");
      }else{

        anim.SetTrigger("Idle");
        changeMenuDisplay(speechbubble, 0);
        Debug.Log("Hand below");
      }

    }
  }
}


The new script is on GitHub.  


Sunday, November 1, 2015

LEAP Motion 3D Jam Entry

I'm working on an entry for the Leap Motion 3D Jam. The Earth Elevator is an educational VR experience where you take an elevator to the center to the earth. The elevator makes several stops along the way to provide you with information about each layer and time to look around.


This project builds on other work I've covered on this blog in these posts:  Using Unity native VR,  Re-centering the avatar and knowing when the health and safety warning has been dismissedSeeing your hands in VR , Hand selection UI prototype,  Raising your hand, and Thought bubbles in a Rift scene using world space canvases.

This demo requires a Rift DK2, a LEAP Motion, Windows 8 or later, and Oculus Runtime 0.7.  If you want to try it out, you can download it from the 3D Jam web site.

I'm considering adding a table with samples from each layer that you can pick up and look at a bit more closely. Don't know if I can get it done in time for the jam, though.

Wednesday, July 29, 2015

Working with the Rift is changing how I dream

The first video game influenced dream I remember having was back in the late eighties. I was obsessed with Tetris and had very vivid dreams of Tetris blocks falling on me. So, it isn’t surprising to me that playing video games can change the way you dream. That said, the specific effect that working with the Rift has had on my dreams did surprise me.

When using the Rift, you are sitting in place and the the world moves around or past you instead of like real-life where you move though the world. I find now in my dreams, no matter what I am dreaming about, there are now two kinds of movement - movement where I dream I am moving through a world and movement where I am still and the world moves around or past me. Perhaps, this kind of dreaming is an attempt by my brain to make Rift movement feel more natural to me? Anyone else dreaming like this?

Tuesday, June 23, 2015

Unity + Leap: Explicit instruction and hand gestures

I have been experimenting a bit with the LEAP and looking at getting objects into the user’s hand. In one of my experiments*, the user holds their hand out flat and a fairy appears. This experiment used explicit instruction written on menus to tell the user what to do.


Explicit instruction worked in that my test users did what I wanted them to - nod and hold their hand out flat. The downside, of course, is that it required them to read instructions which isn’t very immersive or fun. In future experiments, I want to look at implicit instruction, such as having non-player characters perform actions first.

* This demo is now available from the  Leap Motion Gallery.

Notes on getting an object to appear on a user’s hand

Some quick notes on getting the fairy to appear on the user’s hand:

You can find all of the hand models in a scene using:

HandModel[] userHands = handcontroller.GetAllPhysicsHands();

To know if the hand is palm up, you can get the normal vector projecting from the hand relative to the controller, using:

userHands[0].GetPalmNormal()

To know if the hand is open or closed, you can look at the hand’s grab strength. The strength is zero for an open hand, and blends to 1.0 when a grabbing hand pose is recognized.

userHands[0].GetLeapHand().GrabStrength

To know where to place the object, you can get the palm position (relative to the controller), using:

userHands[0].GetPalmPosition()

Wednesday, June 3, 2015

Unity + Leap: Raising Your Hand to Get a Character's Attention

A common interaction in real life is to raise your hand to get someone’s attention. We do it when we are meeting someone in a crowd to help them find us, we do it when we are at school to get the teacher’s attention, and we do it as parents to get our child’s attention so they know that we are there and watching. We also do it when we want to hail a cab or make a bid at an auction. It is a simple enough interaction that babies do it almost instinctively. As simple as raising your hand is, using it as a mechanic in a VR environment brings up some interesting questions. How high should the user raise their hand to trigger the interaction? How long does the user need to have their hand raised? And, what should happen if the application loses hand tracking?

To experiment with this interaction, I created a demo consisting of a single character idling, minding his own business. When the user raises their hand, the character waves back and a speech bubble appears saying “Hello, there!”


Let’s take a look at the demo setup and then look at how testing the user experience went.

Setup

To create the scene I used basic 3D objects (planes, cubes) and a directional light to create a simple room. The character in the scene is a a rigged human character ("Carl") from the Male Character Pack by Mixamo. The speech bubble is created using a world space canvas (see: Thought Bubbles in a Rift scene).  To get my hands in the scene, I used the LeapOVRPlayerController from the Leap Unity Core Assest v.2.2.4 (see: Seeing your hands in VR).

For the character animation, I used the Idle and Wave animations from the Raw Mocap data package for Macanim by Unity Technologies (free animations created from motion capture data) and I created an animation controller for the character to control when he is idling and when he waves back at you. The animation controller has two animation states, Idle and Wave. It also has two triggers that can be used to trigger the transition between each state:


The animation controller for the waving
 character has two states and two triggers.

And, of course, I wrote a script (wavinghello.cs) to detect when the user has raised their hand. The interesting bit of this script is how you know where the user’s hands are and how you know when a hand has been raised high enough  so that you can trigger the appropriate animation. Let's take a look at the script's Update() function:

void Update () {
        HandModel[] userHands = handController.GetAllPhysicsHands(); 
        if (userHands.Length > 0){
          foreach (HandModel models in userHands){

            if (models.GetPalmPosition().y >= centerEyeAnchor.transform.position.y){
                 anim.SetTrigger("Wave");
                 changeMenuDisplay(speechbubble1);
             } else {
                 anim.SetTrigger("Idle");
                 changeMenuDisplay(speechbubble0);
             }
          }

        } else {
            anim.SetTrigger("Idle");
            changeMenuDisplay(speechbubble0);
        }
    }


To get the all of the hands in the scene, the script uses GetAllPhysicsHands() 
from HandController.cs:

  HandModel[] userHands = handController.GetAllPhysicsHands();

GetAllPhysicsHands() returns an array of all Leap physics HandModels for the specified HandController. To get each hand's position, the script uses  GetPalmPosition() which returns the Vector3 position of the HandModel relative to the HandController. The HandController is located at 0, 0, 0 relative to its parent object, the CenterEyeAnchor.

The HandController is a child
 of the CenterEyeAnchor.
The HandController is located at 0, 0, 0
relative to its parent the CenterEyeAnchor.

The CenterEyeAnchor object is used by the Oculus Rift integration scripts to maintain a position directly between the two eye cameras.  As the cameras are the user’s eyes, if the Y value of a HandModel object's position is greater than the Y value of the centerEyeAnchor, we know the user's hand has been raised above eye level.

The user experience

When testing this demo I was looking at how high the user should raise their hand to trigger the interaction, how long the user should have their hand raised, and, what the application should do when it loses hand tracking. Initially, I went with what seemed comfortable for me. I required the users to raise their hand (measured from the center of their palm) to above eye level and I did not require the user's hand to be raised for any specific amount of time. If the Leap lost hand tracking, the application treated it as though all hands were below eye level.

I then grabbed three people to do some testing. The only instruction I gave them was to “raise your hand to get the guy’s attention.” For my first user, the demo worked quite well. He raised his hand and the character waved back as expected. Great so far. My second user was resistant to raising his hand any higher than his nose. He quickly got frustrated as he could not get the guy’s attention. My third user raised his hand and then waved it wildly around so much so that the speech bubble flickered and was unreadable. Quite a range of results for only three users.

For my next iteration, I set  the threshold for raising one’s hand a few centimeters below eye level.

models.GetPalmPosition().y >= centerEyeAnchor.transform.position.y - 0.03f


This worked for my second user as it was low enough that he would trigger the interaction, but not so low that he would accidentally trigger it.

I haven’t done anything to address the third user yet, but whatever I do, waving my hands like a maniac is now part of my my own testing checklist.

I’d love to hear if anyone else is using this type of mechanic and what their experiences are

Friday, March 6, 2015

Quick Look: Unity 5 and the Oculus Unity 4 Integration Package 0.4.4

I downloaded Unity 5 yesterday and gave it a quick trial run with the Oculus Integration Package 0.4.4 for the DK2. To test it out, I first built a quick sample scene using assets found in the Unity standard asset packages. Using that scene, I then tried two methods for getting the scene onto the Rift:
  • Using the OVRPlayerController prefab 
  • Using the First Person Controller prefabs and scripts found in the Unity Standard Assets with the OVRCameraRig prefab
Here’s how those experiments went.

Creating the sample scene

I created a similar sample scene to the one I’ve been using for previous tests - a beach scene using only Unity standard assets. Unity 5 includes a significant refresh of the standard asset packages which is very cool. And nicely for me, they still include palm trees and a sand texture. One change of note is that skyboxes are now set in Window ->Lighting instead of Edit -> Render Settings. Unity 5 comes with a single default skybox which is what I used in this scene. Unity 5 doesn’t include a skyboxes standard asset package, at least not that I found. I did try using the SunnySky box material from the skyboxes package in 4.6 but it does not render nicely.
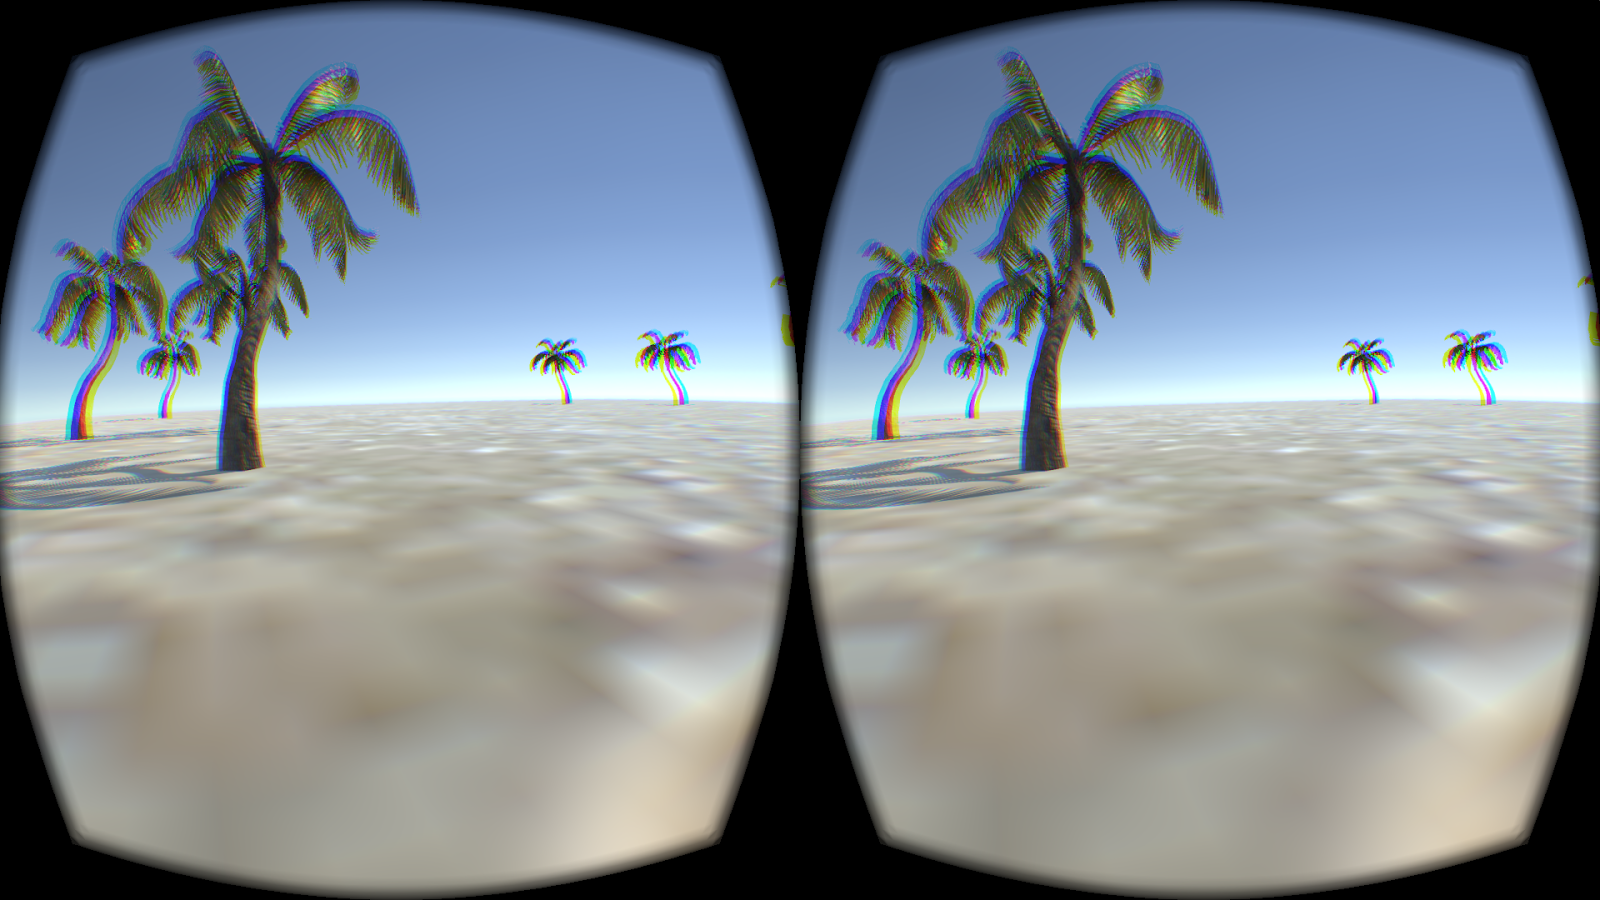
Beach scene created using Unity 5 standard assets 
Notice how  much prettier the palm trees are compared to the 4.6 assets.


Now to get the scene running in the Rift.

Using OVRPlayerController

After downloading and importing the Unity 4 Integration Package 0.4.4, the first thing I tried was just dropping the OVRPlayerController prefab into the scene. The OVRPlayerController character height is 2, so when placing the prefab in the scene I made sure to set the Y value to 1 so it was not colliding with the beach plane. And unlike 4.6, the palm tree assets have colliders attached, so I also made sure my player was placed so that it was not colliding with a palm tree.*

However, before I could build the scene, I needed to address the two errors I was getting:

Assets/OVR/Scripts/Util/OVRMainMenu.cs(250,43): error CS0117: `UnityEngine.RenderMode' does not contain a definition for `World'
Assets/OVR/Scripts/Util/OVRMainMenu.cs(969,43): error CS0117: `UnityEngine.RenderMode' does not contain a definition for `World
'

To get the scene to build, I edited OVRMainMenu.cs and changed:

c.renderMode = RenderMode.World;
to

c.renderMode = RenderMode.WorldSpace;

in the two places where that line occurs. With that done, I was a able to build and run the scene on the DK 2.

Beach scene on the Rift

Running this on a MacBook Pro in mirrored mode I was seeing 60 or so FPS, and in extended mode around 75.

*Actually, I didn’t make sure of that on the first test and at the start of the scene the collision caused the scene to jitter around and it was very unpleasant.

Using the OVRCameraRig with the first person character controller prefabs from the standard assets

My next test was to try to use the OVRCameraRig prefab with the first person character controller from the standard assets. This did not go as well.  With 5.0, there are two First Person Player prefabs: FPSController and RigidbodyFPSController.


The FPSController prefab

The FPSController prefab uses the FirstPersonController.cs script. This script has a number of options, including footstep sounds, head bob and FOV Kick. These options can be great in traditional games but for VR, they can be rather problematic. Head bob and FOV Kick are particularly concerning as these types of motion can be severe motion sickness triggers for some user. Based on that, I didn’t want to spend too much time trying to adapt this script. Instead, I looked at the RigidBodyFPSController.

RigidBodyFPSController

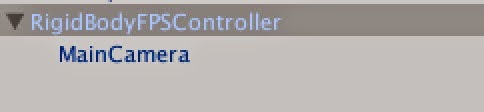
The RigidBodyFPSController prefab consists of the RigidBodyFPSController object with the MainCamera as a child object.


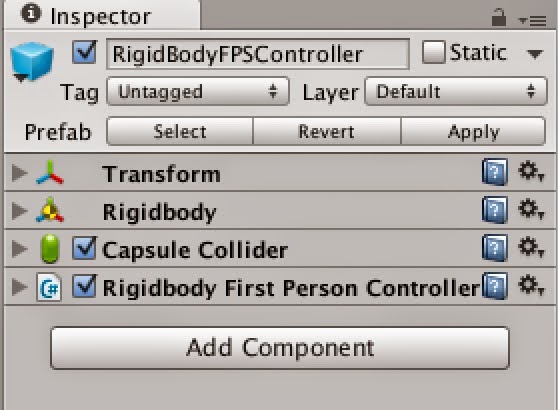
Looking a the RigidBodyFPSController object, you can see that it has a RigidBody, a Capsule Collider and the Rigidbody first person controller script.


To adapt this prefab for use in VR, I first deleted the MainCamera child object and then added the OVRCameraRig in its place.


Note: The MainCamera had a headbob.cs script attached to it. Head bob isn’t something I want in my VR application, and the documentation says that script can be safely disabled or removed.

The Rigidbody First Person Controller script’s Cam variable had been set to the MainCamera. With the MainCamera removed, in the inspector for the script I set it to LeftEyeAnchor.


I then gave the it a test run.

I was seeing similar FPS as in the OVRPlayerController test but the scene was noticeably more jittery. This may be due to using LeftEyeAnchor as the camera but it would require more research to know what is really going on.


Update: March 30, 2015
The build errors appear to be fixed in the 0.5.0.1 Beta version of the Integration Package. When using  0.5.0.1 you need  make sure you have updated to the 0.5.0.1 Beta version of the Runtime Package for it to work. I was not able to build my project until I had updated the Runtime Package as well.

Friday, February 13, 2015

A look a the Leap Motion: Seeing your hands in VR

In many VR demos you are just a floating head in space. For me, this breaks the immersion as it makes me feel like I am not really part of the virtual world. Demos that include a body feel more immersive, but they are also a bit frustrating. I want my avatar’s hands to move when my hands do. To experiment with getting my hands into the scene, I got a Leap Motion controller.

When using the Leap with the Rift, you need to mount it on the Rift itself using a small plastic bracket. You can purchase the bracket from Leap but they also make the model available  on Thingiverse so you can print one out yourself should you have a 3D printer. (I do and I thought that was very cool. I really felt like I was living in the future printing out a part for my VR system.)

Once I got the mount printed out and attached to my Rift and completed the Leap setup instructions, I gave some of the VR demos available a try. Seeing hands in the scene really made it feel a lot more immersive, but what really upped the immersion was seeing hands that looked almost like mine. The leap development package includes a nice variety of hand models (by their naming conventions, I’m a light salt) and that variety is greatly appreciated.

When running the demos, the biggest problems I had with the Leap were false positive hands (extra hands) in the scene, having my hands disappear rather suddenly, and poor tracking of my fingers. Two things that helped were making sure  the Rift cables were  not in front of the Leap controller and removing or covering reflective surfaces in my office (particularly the arm rest on my chair). Even with those changes, having the perfect office setup for the Leap is still a work in progress.

I’ve downloaded the Unity core assets and I’ll be talking more about developing for the Leap using Unity in future posts. Here’s a preview of what I am working on:

Wednesday, February 4, 2015

Unity 4.6: Silent conversation - Detecting head gestures for yes and no

One of the demos that I have really enjoyed is the “Trial of the Rift Drifter” by Aldin Dynamics. In this demo you answer questions by shaking your head for yes and no. This is a great use of the head tracker data beyond changing the user’s point of view. And it is a mechanic that I would like to add to my own applications as it really adds to the immersive feel.

As an example, I updated the thought bubbles scene I created earlier to allow a silent conversation with one of the people in the scene and this blog post will cover exactly what I did.


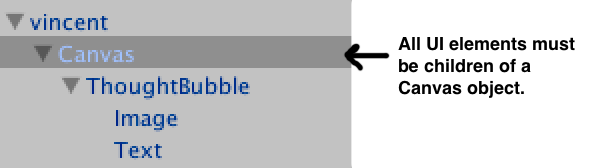
In my scene, I used a world-space canvas to create the thought bubble. This canvas contains a canvas group (ThoughtBubble) which contains an image UI object and a text UI object.

Hierarchy of the world space canvas  
I wanted the text in this canvas to change in response to the user shaking their head yes or no. I looked at a couple of different ways of detecting nods and head shakes, but ultimately went with a solution based on this project by Katsuomi Kobayashi.

To use the gesture recognition solution from this project in my own project, I first added the two Rift Gesture files (RiftGesture.cs and MyMath.cs) to my project and then attached the RiftGesture.cs script to the ThoughtBubble.

When you look at RiftGesture.cs, there are two things to take note of. First, you’ll see that to get the head orientation data, it uses:

OVRPose pose = OVRManager.display.GetHeadPose();
Quaternion q = pose.orientation;


This gets the head pose data from the Rift independent of any other input. When I first looked at adding head gestures, I tried using the transform from one of the cameras on the logic that the camera transform follows the head pose. Using the camera transform turned out to be problematic because the transform can also be affected by input from devices other than the head set (keyboard, mouse, gamepad) resulting in detecting a headshake when the user rotated the avatar using the mouse rather than shaking their head. By using OVRManager.display.GetHeadPose(), it ensures you are only evaluating data from the headset itself.

Second, you will also notice that it uses SendMessage in DetectNod() when a nod has been detected:

SendMessage("TriggerYes", SendMessageOptions.DontRequireReceiver);

and in DetectHeadshake() when a headshake has been detected:

SendMessage("TriggerNo", SendMessageOptions.DontRequireReceiver);

The next step I took was to create a new script (conversation.cs) to handle the conversation. This script contains a bit of setup to get and update the text in the canvas and to make sure that the dialog is visible to the user before it changes. (The canvas groups visibility is set by canvas groups alpha property.) However, most importantly, this script contains the TriggerYes() and TriggerNo() functions that receive the messages sent from the RiftGesture.cs. These functions simply update the text when a nod or headshake message has been received. I attached the conversation.cs script to the ThoughtBubble object and dragged the text object from the canvas to the questionholder so that the script would know which text to update.

Scripts attached to the ThoughtBubble canvas group

At this point I was able to build and test my scene and have a quick telepathic conversation with one of the characters.


Friday, December 12, 2014

Unity 4.6: Thought bubbles in a Rift scene using world space canvases

I’m really liking the new GUI system for 4.6. I had been wanting to play a bit with a comic-book style VR environment and with world space canvases,  and now is the time.


Here's a quick rundown of how I created the character thought bubbles in this scene using world space canvases.

Creating world space canvases

Canvases are the root object for all Unity GUI elements. By default they render to screen space but you also have the option of rendering the canvas in world space, which is exactly what you need for the Rift. To create a canvas, from the Hierarchy menu, select Create > UI > Canvas. When you create a canvas, both a Canvas object and an Event System object are added to your project. All UI elements need to be added as children of a Canvas. Each thought bubble consist of world-space Canvas, and two UI elements - an image and a text box. For organization, I put the UI elements in an empty gameObject called ThoughtBubble.


Note. Hierarchy order is important as UI objects are rendered in the order that they appear in the hierarchy.

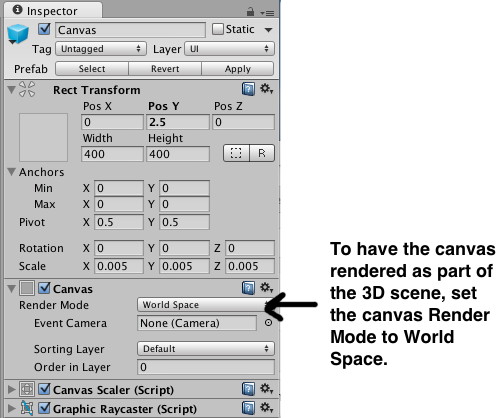
To have the canvas render as part of the 3d scene, in the Inspector for the Canvas, set the Render Mode to World Space.


When you change the render mode to world space, you’ll note that the Rect Transform for the canvas becomes editable. Screen space canvases default to the size of the screen, however, for world space canvases you need to set the size manually to something appropriate to the scene.

Setting canvas position, size, and resolution

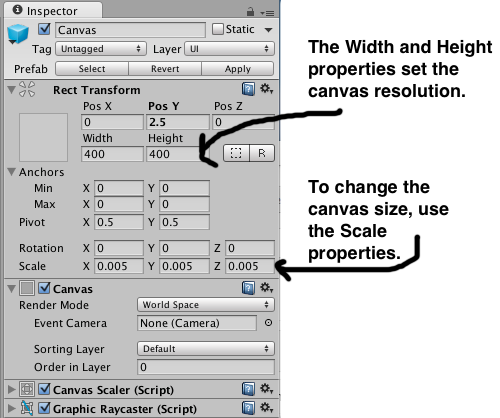
By default the canvas is huge. If you look in the Inspector, you'll see that it has Width and Height properties as well as Scale properties.  The height and width properties are used to control the resolution of the GUI.  (In this scene the Width and Height are set to 400 x 400. The thought bubble image is a 200 X 200 px image and the font used for the Text is 24pt Ariel.)  To change the size of the canvas you need to set the Scale properties. 


To give you an idea of the proportions, the characters in the scene are all just under 2 units high. and the scale of each canvas is set to 0.005 in all directions.  With the canvas a reasonable size, I positioned each canvas just above the character.

Rotating the canvas with the player's view

For the thought bubble to be read from any direction, I attached a script to the Canvas to set the canvas transform to look at the player .

using UnityEngine;
using System.Collections;

public class lookatplayer : MonoBehaviour {
    public Transform target;
    void Update() {
        transform.LookAt(target);
    }
}


Toggling canvas visibility

When you look at a character the thought bubble appears. The thought bubble remains visible until the you look at another character. There were two ways I looked at for toggling the menu visibility - setting the active state of the UI container gameObject (ThoughtBubble) or adding a Canvas Group component to the UI container gameObject and setting the Canvas Group's alpha property. Changing the alpha property seemed easier as I would not need to keep track of inactive gameObjects, so I went with that method.   There is a canvas attached to each character in the scene. The script below is attached to the CenterEyeObject (part of the OVRCameraRig prefab in the Oculus Integration package v. 0.4.4). It uses ray casting to detect which person the user is looking at and then changes the alpha value of the character's attached GUI canvas to toggle the canvas visibility.

using UnityEngine;
using System.Collections;

public class lookatthoughts : MonoBehaviour {
    
    private  GameObject displayedObject = null;
    private  GameObject lookedatObject  = null;


    // Use raycasting to see if a person is being looked 
    // at and if sodisplay the person's attached gui canvas
    void Update () {
        Ray ray = new Ray(transform.positiontransform.forward);
        RaycastHit hit;

        if(Physics.Raycast(rayout hit100)) {
            if (hit.collider.gameObject.tag == "person"){
                lookedatObject = hit.collider.gameObject;
                if (displayedObject == null){
                    displayedObject = lookedatObject;
                    changeMenuDisplay(displayedObject1);
                }else if (displayedObject == lookedatObject){
                    //do nothing
                }else{
                    changeMenuDisplay(displayedObject0);
                    displayedObject = lookedatObject;
                    changeMenuDisplay(displayedObject1);
                }
            }
        } 
    }

    // Toggle the menu display by setting the alpha value 
    // of the canvas group
    void changeMenuDisplay(GameObject menufloat alphavalue){

        Transform tempcanvas = FindTransform(menu.transform"ThoughtBubble");

        if (tempcanvas != null){
            CanvasGroup[] cg;
            cg = tempcanvas.gameObject.GetComponents<CanvasGroup>();
            if (cg != null){
                foreach (CanvasGroup cgs in cg) {
                    cgs.alpha = alphavalue;
                }
            }
        }
    }
    

    // Find a child transform by name
    public static Transform FindTransform(Transform parentstring name)
    {
        if (parent.name.Equals(name)) return parent;
        foreach (Transform child in parent)
        {
            Transform result = FindTransform(childname);
            if (result != nullreturn result;
        }
        return null;
    }
    
}

Thursday, November 6, 2014

Thoughts on an alternative approach to distortion correction in the OpenGL pipeline

Despite some of the bad press it's gotten lately, I quite like OpenGL.  However, it has some serious limitations when dealing with the kind of distortion required for VR.

The problem

VR distortion is required because of the lenses in Ouclus Rift style VR headsets.  Put (very) simply, the lenses provide a wide field of view even though the screen isn't actually that large, and make it possible to focus on the screen even though it's very close to your eyes.

However, the lenses introduce curvature into the images seen through them.  If you render a cube in OpenGL that takes up 40° of your field of view, and look at it through the lenses of the Rift, you'll see curvature in the sides, even though they should be straight.

In order to correct for this, the current approach to correction is to render images to textures, and then apply distortion to the textures.  Think of it as painting a scene on a canvas of latex and then stretching the latex onto a curved surface.  The curvature of the surface is the exact inverse of the curvature introduced by the lenses, so when you look at the result through the lens, it no longer appears distorted.

However, this approach is extremely wasteful.  The required distortion magnifies the center of the image, while shrinking the outer edges.  In order to avoid loss of detail at the center, the source texture you're distorting has to have enough pixels so that at the area of maximum magnification, there is a 1:1 ratio of texture pixels to screen pixels.  But towards the edges, you're shrinking the image, so all your extra rendered pixels are essentially going to waste.  A visual representation of this effect can be seen in my video on dynamic framebuffer scaling below, at about 1:12.


A possible solution...

So how do we render a scene with distortion but without the cost of all those extra pixels that never make it to the screen?  What if we could modify the OpenGL pipeline so that it renders only the pixels actually required?

The modern OpenGL pipeline is extremely configurable, allowing clients to write software for performing most parts of it.  However, one critical piece of the pipeline remains fixed: the rasterizer.  During rendering, the rasterizer is responsible for taking groups of normalized devices coordinates (where the screen is represented as a square with X and Y axes going from -1 to 1) representing a triangle and converting them to lists of pixels which need to be rendered by the fragment shaders.  This is still a fixed function because it's the equivalent of picking 3 points on a piece of graph paper and deciding which boxes are inside the triangle.  It's super easy to implement in hardware, and prior to now there hasn't been a compelling reason to mess with it.

But just as the advent of more complex lighting and surface coloring models made the fixed function vertex and fragment shaders in the old pipeline led to the rise the current model, the needs of VR give us a reason to add programmability to the rasterizer.  

What we need is a way to take the rasterizers traditional output (a set of pixel coordinates) and displace them based on the required distortion.  

What would such a shader look like?  Well, first lets assume that the rasterizer operates in two separate steps.  The first takes the normalized devices coordinates (which are all in the range [-1,1] on both axes) and outputs a set of N values that are still in normalized devices coordinates.  The second step displaces the output of the first step based on the distortion function.

In GLSL terms, the first step takes three vec3 values (representing a triangle) and outputs N vec3 coordinates.  How many N depends on how much of the screen the triangle covers and also the specific resolution of the rasterization operation.  This would not be the same resolution as the screen for the same reason that we render to a larger than screen resolution texture in the current distortion method.  This component would remain in the fixed function pipeline.  It's basically the same as the graph paper example, but with a specific coordinate system.  

The second step would be programmable.  It would consist of a shader with a single vec2 input and a single vec2 output, and would be run for every output of the first step (the vec3's become vec2's because at this point in the pipeline we aren't interacting with depth, so we only needs the xy values of the previous step).  

in vec2 sourceCoordinate;
out vec2 distortedCoordinate;

void main() {
  // Use the distortion function (or a pre-baked structure) to 
  // compute the output coordinate based on 
  // the input coordinate
}

Essentially this is just a shader that says "If you were going to put this pixel on the screen here, you should instead put it here".  This gives the client the displace the pixels that make up the triangle in exactly the same way they would be displaced using the texture distortion method currently used, but without the cost of running so many extra pixels through the pipeline.  

Once OpenGL has all the output coordinates, it can map them to actual screen coordinates.  Where more than one result maps to a single screen coordinate, OpenGL can blend the source pixels together based on each's level of contribution, and send the results as a single set of attributes to the fragment shader.  

The application of such a rasterization shader would be orthogonal to the vertex/fragment/geometry/tesselation shaders, similar to the way compute shaders are independent.   Binding and unbind a raster shader would have no impact on the currently bound vertex/fragment/geometry/tesselation shader, and vice versa.  

Chroma correction

Physical displacement of the pixels is only one part of distortion correction.  The other portion is correction for chromatic aberration, which this approach doesn't cover.

One approach would be to have the raster shader output three different coordinates, one for each color channel.  This isn't appealing because the likely outcome is that the pipeline then has to run the fragment shader multiple times, grabbing only one color channel from each run.  Since avoiding running the fragment shader operations more than we have to is the whole point of this exercise, this is unappealing.

Another approach is to add an additional shader to the program that specifically provides the chroma offset for each pixel.  In the same way you must have both a vertex and a fragment shader to create a rendering program in OpenGL, a distortion correction shader might require both a raster and a chroma shader.  This isn't ideal, because only the green channel would be perfectly computed for the output pixel it covers, while the red and blue pixels would be covering either slightly more or slightly less of the screen than they actually should be.  Still it's likely that this imperfection would be well below the level of human perception, so maybe it's a reasonable compromise.

Issues

Cracks
You want to avoid situations where two pixels are adjacent in the raster shader but the outputs have a gap between them when mapped to the screen pixels.  Similar to the way we use a higher resolution than the screen for textures now, we would use a higher resolution than the screen for the rasterization step, thus ensuring that at the area of greatest magnification due to distortion, no two two adjacent input pixels cease to be adjacent when mapped to actual physical screen resolution

Merging
An unavoidable consequence of distortion, even without the above resolution increase is that pixels that are adjacent in the raster shader inputs will end up with their outputs mapping to the same pixel.  

Cost 
Depending on the kind of distortion required for a given lens, the calculations called for in the raster shader might be quite complex, and certainly not the kind of thing you'd want to be doing for every pixel of every triangle.  However, that's a fairly easy problem to solve.  When binding a distortion program, the OpenGL driver could precompute the distortion for every pixel, as well as precompute the weight for each rasterizer output pixel relative to the physical screen pixel it eventually gets mapped to.  This computation would only need to be done once for any given raster shader / raster raster resolution / viewport resolution required.  If OpenGL can be told about symmetry even more optimization is possible.  

You end up doing a lot more linear interpolation among vertex attributes during the rasterization state, but all this computation is still essentially the same kind of work the existing rasterization stage already does, and far less costly than a complex lighting shader executed for a pixel that never gets displayed. 

Next steps

  • Writing up something less off the cuff
  • Creating a draft specification for what the actual OpenGL interface would look like
  • Investigating a software OpenGL implementation like Mesa and seeing how hard it would be to prototype an implementation
  • Pester nVidia for a debug driver I can experiment with
  • Learn how to write a shader compiler
  • Maybe figure out some way to make someone else do all this


Monday, August 4, 2014

0.4 SDK: Users of unknown gender now have a gender of “Unknown”

Oculus recently released the 0.4 version of the SDK.  I am primarily a Mac developer and the fact that it isn’t available for the Mac yet is a big disappointment to me. So while I am impatiently waiting for the Mac version, I’ll poke around the Windows version. As the default profile settings were an irritation to me previously, I checked to see if Oculus made changes to the default profile settings and I am pleased to see that they have:

#define OVR_DEFAULT_GENDER                  "Unknown"

That’s right. Users who have not yet created a profile are no longer assumed to be “male”. Instead the default matches reality - when the user’s gender is unknown because the user hasn’t specified a gender, the SDK now returns a gender of “Unknown”.

This is a good step as you will no longer get false data from the SDK. Let's take a closer look at the profile default values

// Default measurements empirically determined at Oculus to make us happy
// The neck model numbers were derived as an average of the male and female averages from ANSUR-88
// NECK_TO_EYE_HORIZONTAL = H22 - H43 = INFRAORBITALE_BACK_OF_HEAD - TRAGION_BACK_OF_HEAD
// NECK_TO_EYE_VERTICAL = H21 - H15 = GONION_TOP_OF_HEAD - ECTOORBITALE_TOP_OF_HEAD
// These were determined to be the best in a small user study, clearly beating out the previous default values
#define OVR_DEFAULT_GENDER                  "Unknown"
#define OVR_DEFAULT_PLAYER_HEIGHT           1.778f
#define OVR_DEFAULT_EYE_HEIGHT              1.675f
#define OVR_DEFAULT_IPD                     0.064f
#define OVR_DEFAULT_NECK_TO_EYE_HORIZONTAL  0.0805f
#define OVR_DEFAULT_NECK_TO_EYE_VERTICAL    0.075f

#define OVR_DEFAULT_EYE_RELIEF_DIAL         3


It is also good to see that the "neck model numbers were derived as an average of the male and female averages." However, the height here remains as it has in past SDK versions at 1.778f - the average height of an adult male in the US. I'm a little wary of this value as Oculus doesn't indicate how varied the user pool used to determine this value was. They simply say "a small user study." Was this a varied user pool comprised equally of men and women? How varied were the heights of those in the user pool? Without that information or further study, I can't be sure that these values don't introduce bias and it is something I will keep track of in my own user tests.

I've been keeping such a close eye on this issue because I feel that what the writer Octavia Butler said about science fiction applies here and now to VR.

 "There are no real walls around science fiction. We can build them, but they’re not there naturally."
-- Octavia Butler

 There are no real walls around VR. Let's do what we can to not build those walls. VR is for everyone.